


Narwhal is a disaggregated inference framework that automatically hot-swaps prefill and decode roles as demand changes, without reloading model weights. It runs on a single GPU or across multi-node deployments.
| Capability | Behavior | Guide |
|---|---|---|
| Role hot-swap | Reassigns prefill and decode roles across a fixed GPU fleet, with NIXL key-value (KV) transfer between them |  |
| Serving | Serves completion and chat requests, streamed or buffered, with latency-aware admission |  |
| Fault tolerance | Fails over to a warm-standby router and readmits engines against their live process generation |  |
| Measurement | Profiles engines, runs ordered benchmark points, and keeps the evidence from each point |  |
| Observability | Exports router and engine metrics to Prometheus and a provisioned Grafana dashboard |  |
| Operator tooling | Validates fleet files offline and collects private diagnostic bundles |  |
| Development mode | Runs two to eight engines on one workstation under Ubuntu or WSL2, on a GPU or the CPU |  |
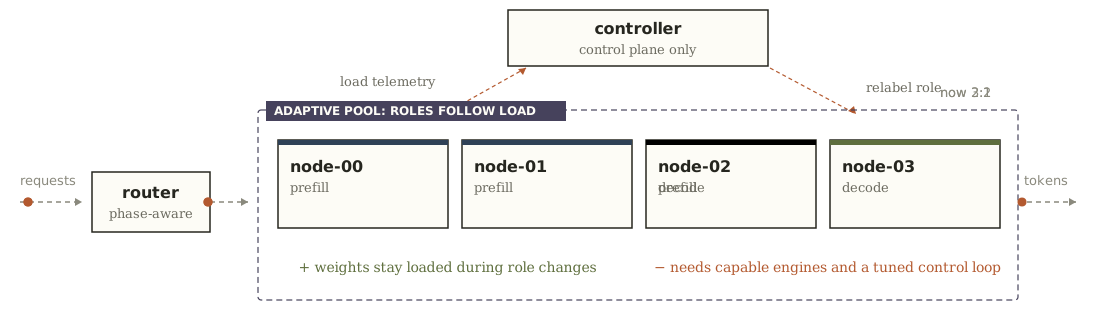
The role controller scores the current role split and each adjacent split, one engine move away. It uses measured engine profiles, offered demand, and resident work, and moves one engine only when the worst projected SLO ratio improves and every role, lifecycle, and resident-work guard passes. New requests follow the revised split, and resident requests finish on their assigned engines.

Install on Linux with Python 3.11 or newer:
python3 -m venv .venv
source .venv/bin/activate
python -m pip install narwhal-inference
narwhal-serve --version
narwhal --help
The wheel installs narwhal, narwhal-engine, narwhal-serve, narwhal-attest, narwhal-profile, and narwhal-check. To verify the installation, follow Installing from PyPI. For each command's options, use the CLI reference.
Narwhal dev runs four llama.cpp engines and a router on one Linux or WSL2 machine, on an NVIDIA GPU or on the CPU alone. Setup downloads the engine and a model under one billion parameters, 0.3 GB with the CPU build of the engine and 1.0 GB with the CUDA 12 build.
narwhal dev up
narwhal dev ask "What is the capital of France?"
narwhal dev ask --repeat 2000 --concurrency 8 --max-tokens 200
narwhal dev watch
narwhal dev down --remove
up downloads the engine and the model on its first run, then starts the fleet. down --remove stops it and deletes the downloads. ask prints the reply and the engines that served its prefill and decode. watch shows each engine's role and load, and each role switch the router makes under the concurrent requests.
Narwhal dev also runs vLLM and SGLang engines on one NVIDIA GPU with narwhal dev init, with the attestation, profiling and KV transfer checks a deployed fleet uses.


Run the deployment gates in Deploying a fleet from a management workstation.
The documentation site covers installation, deployment, operation, measurement, and reference tasks.
Narwhal's scheduling algorithms are based on Arrow: Adaptive Scheduling Mechanisms for Disaggregated LLM Inference Architecture by Wu et al. (2025).